HKEx Filings
io.github.simonplmak-cloudPublished by GitHub account simonplmak-cloudv2.4.1Updated Oct 2, 2026
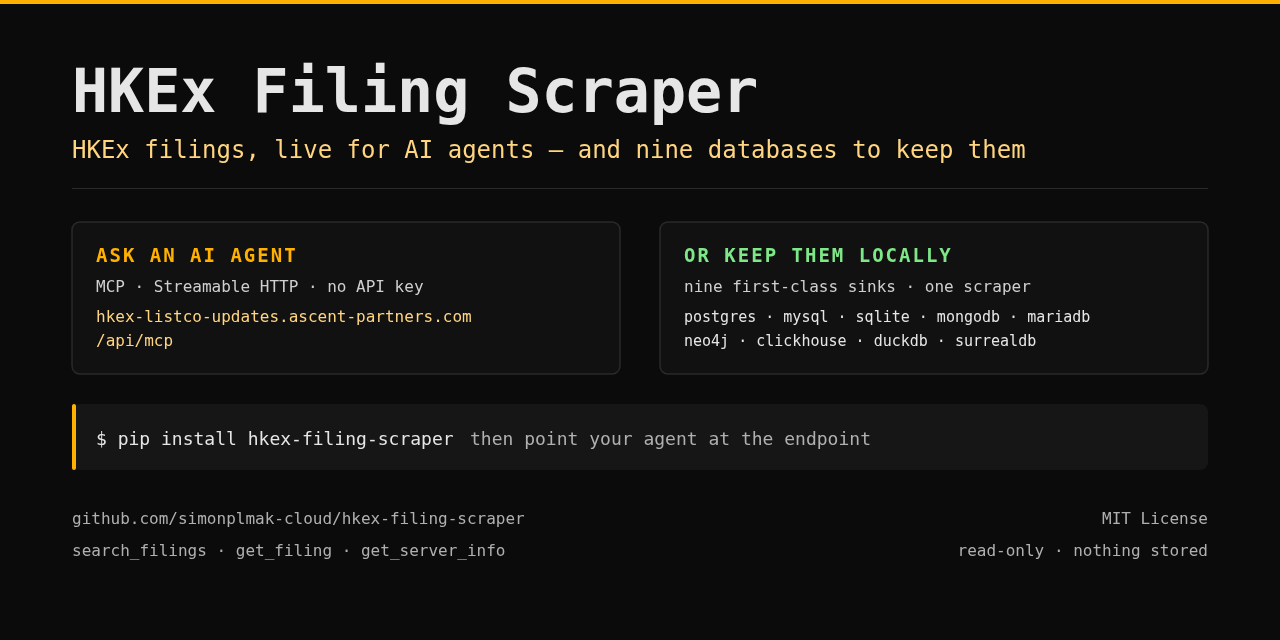
Live HKEx (Hong Kong Stock Exchange) regulatory filings for AI agents.
The publisher's own server: SEC Filings
Overview
Read-only MCP access to live Hong Kong Stock Exchange (HKEx) regulatory filings, letting an assistant search, browse and extract filing text and tables.
- What you can do
- Search filings within a window of at most 31 days, filtered by stock code, title, document type, category or stock name
- Browse what a date window contains through filing facets
- Download a single filing document and extract its text and tables
- Report server information about the gateway itself
- A local stdio variant exposes a wider tool catalog over a stored corpus
- When to use it
- Useful when an assistant needs current or historical HKEx announcements, interim reports or other listed-company filings for research, compliance checks or retrieval over a local corpus, without building a scraper.
- Requirements
- Either the hosted Streamable HTTP endpoint (no API key) or a local install of the PyPI package hkex-filing-scraper, run with uvx or pip; the local pipeline needs a DATABASE_TARGET setting and, for non-SQLite sinks, connection details such as POSTGRES_DSN. Network access to HKEx is required.
Installation
In SourceWeft
- Open HKEx Filings in the dashboard and add it to a workspace.
- Enable the server for the chats that should use its tools.
Web executable via Streamable HTTP. Remote servers run from the web runtime once configured in a workspace.
Use with an agent
Paste this prompt into Claude Code, Codex, Cursor or another agent — or into SourceWeft chat. The agent reads this server's install guide, shows you its publisher, endpoint and sign-in, and adds it to your client once you agree. Keys never go into a command.
Read https://sourceweft.com/mcp/io.github.simonplmak-cloud%2Fhkex-filings/install.md and connect the MCP server it describes to my client. Before changing any config, show me its publisher, endpoint and sign-in method and wait for my OK. Never put an API key in a command or in a file I would commit; ask me where it should come from.Other MCP clients
Add this to your client's mcpServers config.
{
  "mcpServers": {
    "hkex-filings": {
      "type": "http",
      "url": "https://hkex-listco-updates.ascent-partners.com/api/mcp"
    }
  }
}
README
HKEx Filing Scraper
An open-source scraper for 25+ years of HKEx regulatory filings — into any of nine databases, with full-text extraction, graph linking, and a read-only MCP server for AI agents.
[HKEx Filing Scraper — one scraper, many databases]
[CI] [MCP Registry] [Glama MCP] [GitHub Release] [PyPI] [Python 3.10+] [Docs] [MCP] [Ruff] [License: MIT]
Overview
The US has EDGAR full-text search. Japan has EDINET. Hong Kong has a search form that returns one page at a time. There is no bulk, machine-readable, full-text corpus of HKEx filings. This builds one.
An open-source Python tool that scrapes 25+ years of Hong Kong Stock Exchange (HKEx) regulatory filings and ingests them into any combination of nine databases — with full-text and table extraction, chunk-level coverage, optional graph linking, and a read-only MCP server so AI agents can query the corpus or the live site.
It speaks the undocumented HKEx JSON API directly, which is faster and more resilient than driving a browser.
Vendors & Integrations
Databases — nine first-class destinations, in documented popularity order (see the support matrix):
- PostgreSQL — production-grade open-source relational
- MySQL / MariaDB — GPL relational servers, one driver
- SQLite — zero-server file database, no install needed
- MongoDB — document database
- Neo4j — property-graph database
- ClickHouse — columnar analytics engine
- DuckDB — in-process analytical engine
- SurrealDB — multi-model graph + document database
AI clients — any MCP-capable agent; ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode, Manus, and Perplexity.
Available on — PyPI · Glama · MCP Registry · hosted gateway.
Two Ways to Use It
[Example: install, scrape filings into SQLite, then query the hosted MCP gateway from an AI agent]
Use the Hosted MCP Gateway
POST, Streamable HTTP, no API key:
Four read-only tools: get_server_info, search_filings (a window of at most 31 days, with
optional stock-code, title, document-type, category, and stock-name filters),
list_filing_facets (browse what a window contains), and get_filing (downloads one
document and extracts its text and tables).
[Two ways to reach HKEx filings from an AI agent: the hosted MCP gateway or the local stdio server]
Point a client at it — for example opencode:
Then ask:
Ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode,
Manus, and Perplexity is in AI agent support — and for a stored corpus,
the stdio MCP server exposes a wider tool catalog and is published on
Glama. The gateway is listed
in the official MCP Registry as
com.ascent-partners/hkex-filings.
Featured on Glama — the read-only stdio MCP server is also published on Glama, where Glama scans the built server and scores tool-definition quality (currently 4.7/5).
Quick Start (≤ 5 minutes)
Fastest path: no install — use the hosted gateway at
https://hkex-listco-updates.ascent-partners.com/api/mcp (Streamable HTTP), or install and run
locally:
Optional extras: excel, postgres, mysql, duckdb, mongodb, clickhouse, neo4j,
mcp, pdf, all, dev.
DATABASE_TARGET is an ordered, comma-separated list of sink ids; the order decides which
sink serves reads. To start with no server:
hkex-scraper runs the full pipeline (metadata + documents + graph); hkex-scraper --full-history covers everything since April 1999. The schema is created automatically.
Full install options and per-sink settings are in Getting started.
Database Support
Every sink is a first-class destination; rows are in documented popularity order. The full matrix — licenses, capability differences, per-engine notes — is in Database sinks.
¹ Source-available, not OSI-approved — labeled exceptions per ADR 0003.
Valid sink ids, in documented order: postgres, mysql, sqlite, mongodb, mariadb, neo4j, clickhouse, duckdb, surrealdb. Set one variable and the same run feeds every sink:
How This Compares
Four ways to get HKEx filings, and what each one costs you.
If you need licensed, redistributable, SLA-backed data, buy the feed. If you need a complete local corpus for research, compliance, or RAG, this replaces the pipeline you would otherwise write yourself.
How It Works
- Phase 1 scrapes filing metadata through a JSF session, splitting the range into monthly
chunks and deduplicating on a 16-character MD5
filingId. - Phase 2 downloads each filing's PDF/HTML/Excel document, extracts text and tables to Markdown, and writes the payload.
- Graph linking (optional) writes
has_filingandreferences_filingedges whenCOMPANY_TABLEis set. - Failure isolation — a failure on one sink is logged and counted but never blocks another; the run exits non-zero if any configured sink failed.
Deeper detail: Architecture · ADR 0002.
HKEx API session
Data model
exchange_filing and scrape_coverage are SCHEMAFULL; has_filing /
references_filing are the graph edges written by graph.py.
Sink contract and read routing
Features
- Fast API scraping — direct HKEx JSON API; no browser or Selenium.
- Full history — every filing from April 1999 to today, with chunk-level coverage checks.
- Document processing — PDF/HTML/Excel text and structured tables, extracted to Markdown.
- Multi-sink — any ordered combination of nine databases, each with native idempotent upserts.
- AI-ready — a hosted live MCP gateway plus a local stdio MCP server.
- Resumable and observable — batching, parallel downloads, stalled-job detection, per-sink
counters, and
--coverage-report/--parity-report/--verify. - Optional dependencies — the core is
requests+beautifulsoup4; drivers and document extraction are extras with graceful fallbacks.
Documentation
- Getting started · Configuration · CLI
- Database sinks (matrix) — PostgreSQL, MySQL/MariaDB, SQLite, MongoDB, Neo4j, ClickHouse, DuckDB, SurrealDB
- Live MCP gateway · AI agent support · MCP server
- Architecture · Troubleshooting · Testing
- Roadmap · De-risking register · Upgrading
- What's new · Releasing · Legal & Terms of Use · Changelog
- Docs site: https://hkex-listco-updates.ascent-partners.com/ · Try it locally (
examples/)
Development
Tests are pure unit tests; SQLite and DuckDB contract tests run in-process, and integration tests that need a server are skipped unless that sink is configured. See Testing.
CI and deployment run through the APG workbench pipeline.
The deploy smoke check probes the public hostname through the balancer, not a local port.
Contributing
See CONTRIBUTING.md; report security issues per SECURITY.md. Ideas and questions are welcome in Discussions.
Built by Ascent Partners.
If this saves you time, a ⭐ on GitHub helps others find it.
Use with Context7
Up-to-date HKEx Filing Scraper documentation is indexed on Context7, so coding agents can pull it into context on demand. With the Context7 MCP server or ctx7 CLI installed, name the library in your prompt:
License
MIT — see LICENSE. That covers this project's code only; optional dependencies
carry their own licenses, notably the pdf extra (PyMuPDF / pymupdf4llm), which is
AGPL-3.0 and deliberately excluded from .[all]. See
docs/legal.md.
Data & Terms of Use: this is a research tool for the undocumented HKEx JSON API, and it is not affiliated with or endorsed by HKEx. Commercial redistribution of HKEx data may require a licensed HKEx feed; see docs/legal.md.
Source: README.md at commit 75b7d61
Tools
0Version history
2- v2.4.1LatestOct 1, 2026
- v2.4.0Sep 20, 2026
Score
50% of the applicable checks met
How complete this listing is, computed from the registry entry, the endpoint and public sources. Not a rating of the server and not a statement that it is safe or working today: reachability is a dated check, and no installs or reviews go into the score.
- Reached in the last 30 daysRequired25 pts
Keep the endpoint answering the MCP handshake; SourceWeft probes it every 30 days.
- Auth declaredRequired10 pts
Declare the credential headers in the registry entry, or keep the endpoint answering the probe so its auth can be classified.
- Tools listed15 pts
Answer tools/list without a credential, or ship a package that starts in a sandbox without one.
- DescriptionRequired15 pts
- Logo10 pts
- Documentation15 pts
- License10 pts
Other Filings integrations
SEC Filings
tools.filingsOfficial publisher
Reads public SEC EDGAR filings, reported XBRL financial facts and sampled filing comparisons, with source URLs and accession numbers.

SEC filings
Published by GitHub account ladanyin
Remote MCP server that lets an assistant pull excerpts of a US company's latest SEC 10-K, 10-Q or 8-K and its latest full-year revenue or net income.

getfilings: the Filings door
Published by GitHub account allooloo
Remote MCP router that returns an issuer's signed, receipted regulatory filings and releases for a date range, plus issuer lookup and market node listing.

US SEC EDGAR Filings, FDIC Bank Solvency & EPA/OSHA
Published by GitHub account jesleytassili-glitch
US SEC EDGAR Filings, FDIC Bank Solvency & EPA/OSHA's hosted MCP server; credential required; Streamable HTTP.

SEV — Company Discovery from SEC Filings
Published by GitHub account ETSquareAI
Local MCP server that turns a research question into ranked companies with vetted SEC 10-K/10-Q passages and financials.